TL;DR
Baidu released Unlimited-OCR, a 3-billion-parameter AI model capable of parsing entire multi-page documents in a single pass. It introduces a new memory mechanism that maintains constant GPU memory, enabling faster and more accurate long-document OCR without splitting pages.
Baidu has open-sourced Unlimited-OCR, a groundbreaking AI model designed to process entire multi-page documents in a single forward pass, marking a significant advance in PDF digitalization. The model, released under an MIT license, features a novel memory mechanism that enables faster and more accurate OCR of long documents, reducing the need for page splitting and improving reading order integrity.

Turn your quiet moments into listening time
- Thousands of audiobooks, podcasts and originals
- Listen on your phone, tablet or Echo — also offline
- Cancel anytime
The model, with 3 billion parameters and support for standard frameworks like Transformers and Docker, builds on Baidu’s prior OCR work, notably DeepSeek-OCR. It incorporates a new attention mechanism called Reference Sliding Window Attention (R-SWA), which replaces traditional attention cache growth with a fixed-size memory, allowing the model to parse dozens of pages in a single pass without increasing latency or memory usage.
According to Baidu’s technical report, Unlimited-OCR achieves a 12.7% speed increase over previous models such as DeepSeek-OCR on benchmarks like OmniDocBench. It scores above 93 on overall document parsing accuracy and maintains a low error rate across long documents, with less than 0.11 error after processing 40+ pages. Despite some viral claims, Baidu clarifies that the model has approximately 8,400 downloads in the last month, far from the 1.9 million figure circulated online.
Implications for Long-Document OCR and PDF Processing
The introduction of Unlimited-OCR represents a major step forward in AI-powered document digitization, especially for lengthy PDFs, books, and technical papers. Its ability to process entire documents in a single pass reduces errors related to page splitting and improves reading order accuracy. This development could streamline workflows in industries relying heavily on document digitization, such as legal, academic, and governmental sectors, by enabling faster, more reliable OCR without extensive pre-processing or splitting.
Products Worth Considering
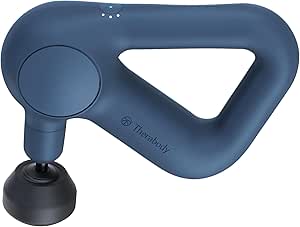
Therabody Theragun Relief Massage Gun, 3-Speed, Navy

Hyperice Hypervolt Go 3 Percussion Massage Gun

Fitbit Sense 2 Smartwatch – Shadow Grey/Graphite
As an affiliate, we earn on qualifying purchases.
Baidu’s OCR Development and Architectural Advances
Prior to this release, OCR models typically processed documents page-by-page, which introduced issues like broken tables and misplaced references. Baidu’s earlier work, DeepSeek-OCR, already demonstrated high accuracy but was limited by linear cache growth, which slowed processing for long documents. The new architecture, R-SWA, addresses this by maintaining a constant memory footprint, a notable engineering achievement that builds on Baidu’s open-source OCR lineage and enhances its competitive edge against models from other AI firms like PaddleOCR and Zhipu.
“Unlimited-OCR introduces a fixed-size memory mechanism that allows parsing of entire multi-page documents in one pass, significantly improving speed and accuracy for long documents.”
— Baidu Research Team
Unresolved Questions About Real-World Deployment
It remains unclear how Unlimited-OCR performs outside controlled benchmarks, especially on diverse, real-world documents with complex layouts. The model’s long-term robustness, integration challenges, and comparative performance against commercial cloud OCR solutions are still to be evaluated in practical settings. Additionally, the actual user adoption rate and impact on existing OCR workflows are not yet confirmed.
Next Steps for Adoption and Benchmarking
Baidu is expected to demonstrate Unlimited-OCR in real-world applications and gather user feedback. Further independent benchmarking on diverse datasets will clarify its practical advantages over existing models. The company may also release updates or optimized versions, and competitors are likely to respond with similar innovations, shaping the future landscape of AI-based PDF digitalization.
Key Questions
What makes Unlimited-OCR different from previous OCR models?
It uses a novel memory mechanism called Reference Sliding Window Attention, which maintains a fixed memory size, allowing the model to process entire multi-page documents in one pass without slowing down or increasing memory usage.
Can Unlimited-OCR handle complex layouts like tables and cross-references?
Preliminary results suggest it performs well on long documents, but its effectiveness on complex layouts like multi-page tables or heavily formatted documents remains to be fully tested in real-world scenarios.
Is this model available for commercial use?
Yes, Baidu has open-sourced Unlimited-OCR under an MIT license, with support for local deployment using frameworks like Docker and Hugging Face.
How does this development impact existing OCR solutions?
It offers a new approach that could reduce the need for page splitting, improve accuracy on long documents, and speed up processing, potentially challenging cloud-based OCR services and prompting industry shifts toward self-hosted models.
What are the limitations of Unlimited-OCR at this stage?
Its performance outside benchmark tests is not yet confirmed, and real-world documents with complex layouts may pose challenges. Further testing is required to validate its robustness and integration capabilities.
Source: ThorstenMeyerAI.com