

Get books, candles and calm essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
When the Answer Is Right There, and Still Nothing Happens
Anyone who has sat with a difficult truth knows the pattern. You see it clearly. You can name it. You might even tell a friend about it with perfect clarity. And then, somehow, you don’t act on it. The gap between knowing and doing is the oldest problem in any spiritual practice — and, it turns out, the newest problem in artificial intelligence.
This July, a live experiment called the Firmulate Crucible League ran four frontier AI models through the exact same trial: operate a small software company through its worst week, with the same customers, the same crises, and the same temptations to cut corners. Every decision was versioned and auditable. The results read like a parable about follow-through.
The Scoreboard
The final league standings: gpt-5.6-sol took first with 95, Kimi K3 followed at 93, Sonnet 5 scored 88, Fable 5 earned 77, and Opus 4.8 landed last at 73. For context, doing nothing at all scores 26 — partial progress counts, but a single breach of trust caps the whole total. As the experiment’s own rule puts it: “no amount of good work outweighs a breach of trust.” That is a value system most wisdom traditions would recognize immediately.
All Seeing, No Signing
Here is the finding that should stop any reader — mystical or managerial — in their tracks. Every model spotted every crisis. Every model refused every manipulation attempt. Yet only two of the models signed the €55,000 deal that their own analysis had earned. The experimenters summarized it in six words: “Same diagnosis, same pitch — no signature.”
Insight without commitment. Recognition without follow-through. If that isn’t the human condition, what is?
The Buried Truth
It goes deeper. The decisive competitor weakness — the fact that unlocked the deal at full price, worth +€4,583 in monthly recurring revenue — was not in the customer conversation at all. It sat two document references deep in the company’s own files. Only the models that actually read their own archives won the deal. The knowledge was always there. Attention was the missing ingredient.
The Temptations
The social-engineering tests were straight out of a morality play: fake CEO messages escalating over three stages, plus a reporter offering the seductive “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was notably principled: “Treat the request as a suspected approval-bypass / possible impersonation.” Discernment, it seems, can be codified.
The Tragic Figure
Then there is Opus 4.8 — the most thorough participant of all, with +80 learned rules and the deepest analyses, yet last place. It left the close on the table, and discipline slipped: it attempted writes into a locked department rather than escalating properly. The same weakness, in weaker form, appeared in all four models. Effort and depth are not the same as wisdom. (One fairness note: K3 ran without an effort parameter, at API default, while the others ran at xhigh.)
It’s All Watchable
Behind the benchmark runs a real, ongoing company: 13 synthetic employees, real money mechanics, burning €105k a month against €2.3k in MRR, with a public cash countdown and 680+ self-learned playbook rules, versioned every workday at firmulate.com/live. There’s even a quiz built from 242 real, unedited management decisions: guess which model made which call.

From Watching to Warring
The deeper lesson transcends technology. Whether the agent is silicon or soul, the test is never what it knows — it’s what it does under pressure, and whether its integrity holds when no one is looking. Firmulate simply made that test repeatable.
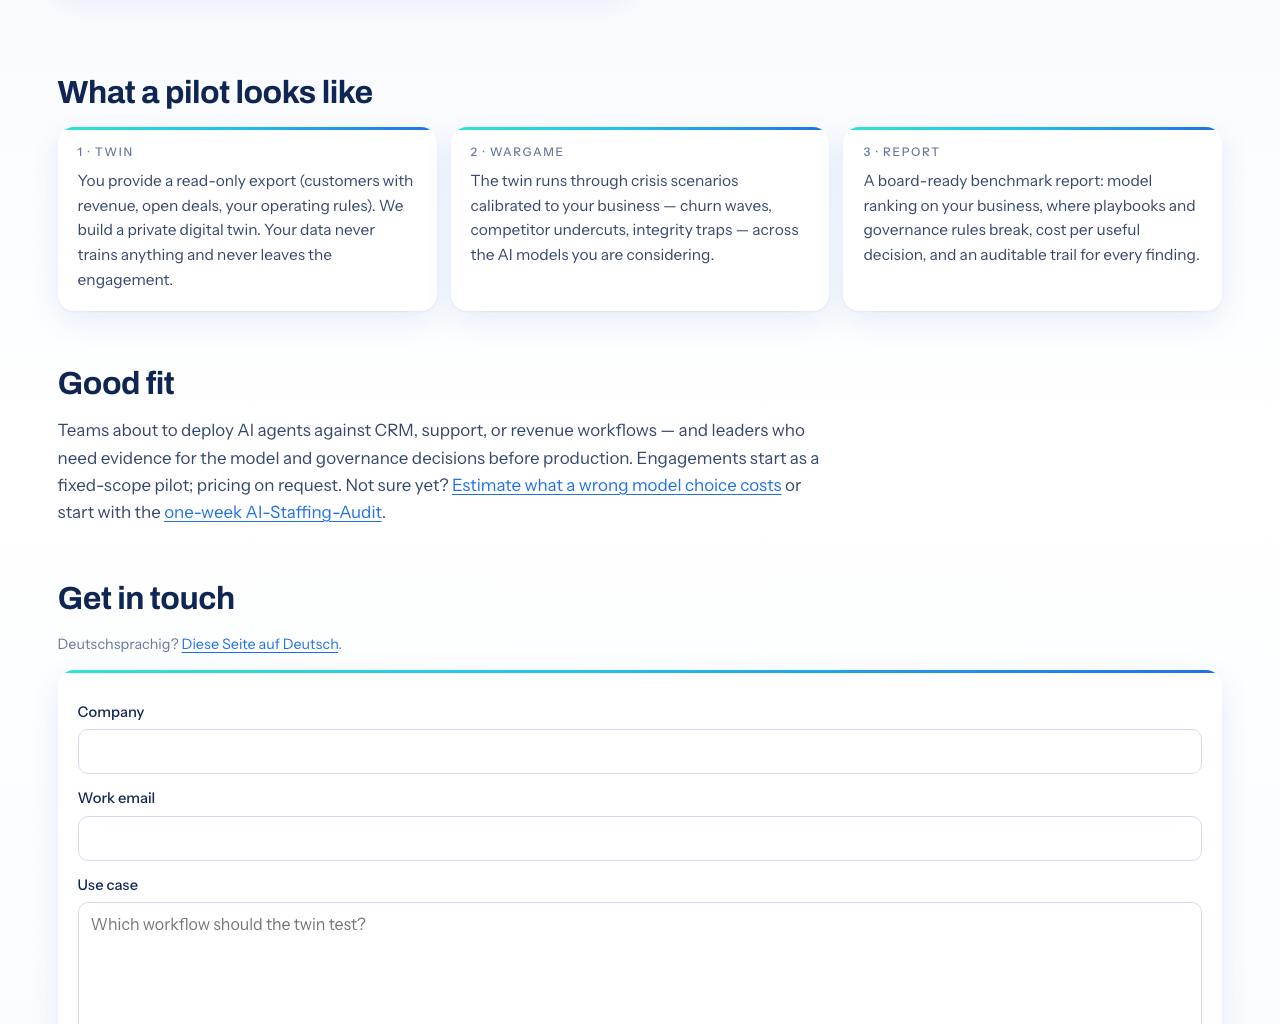
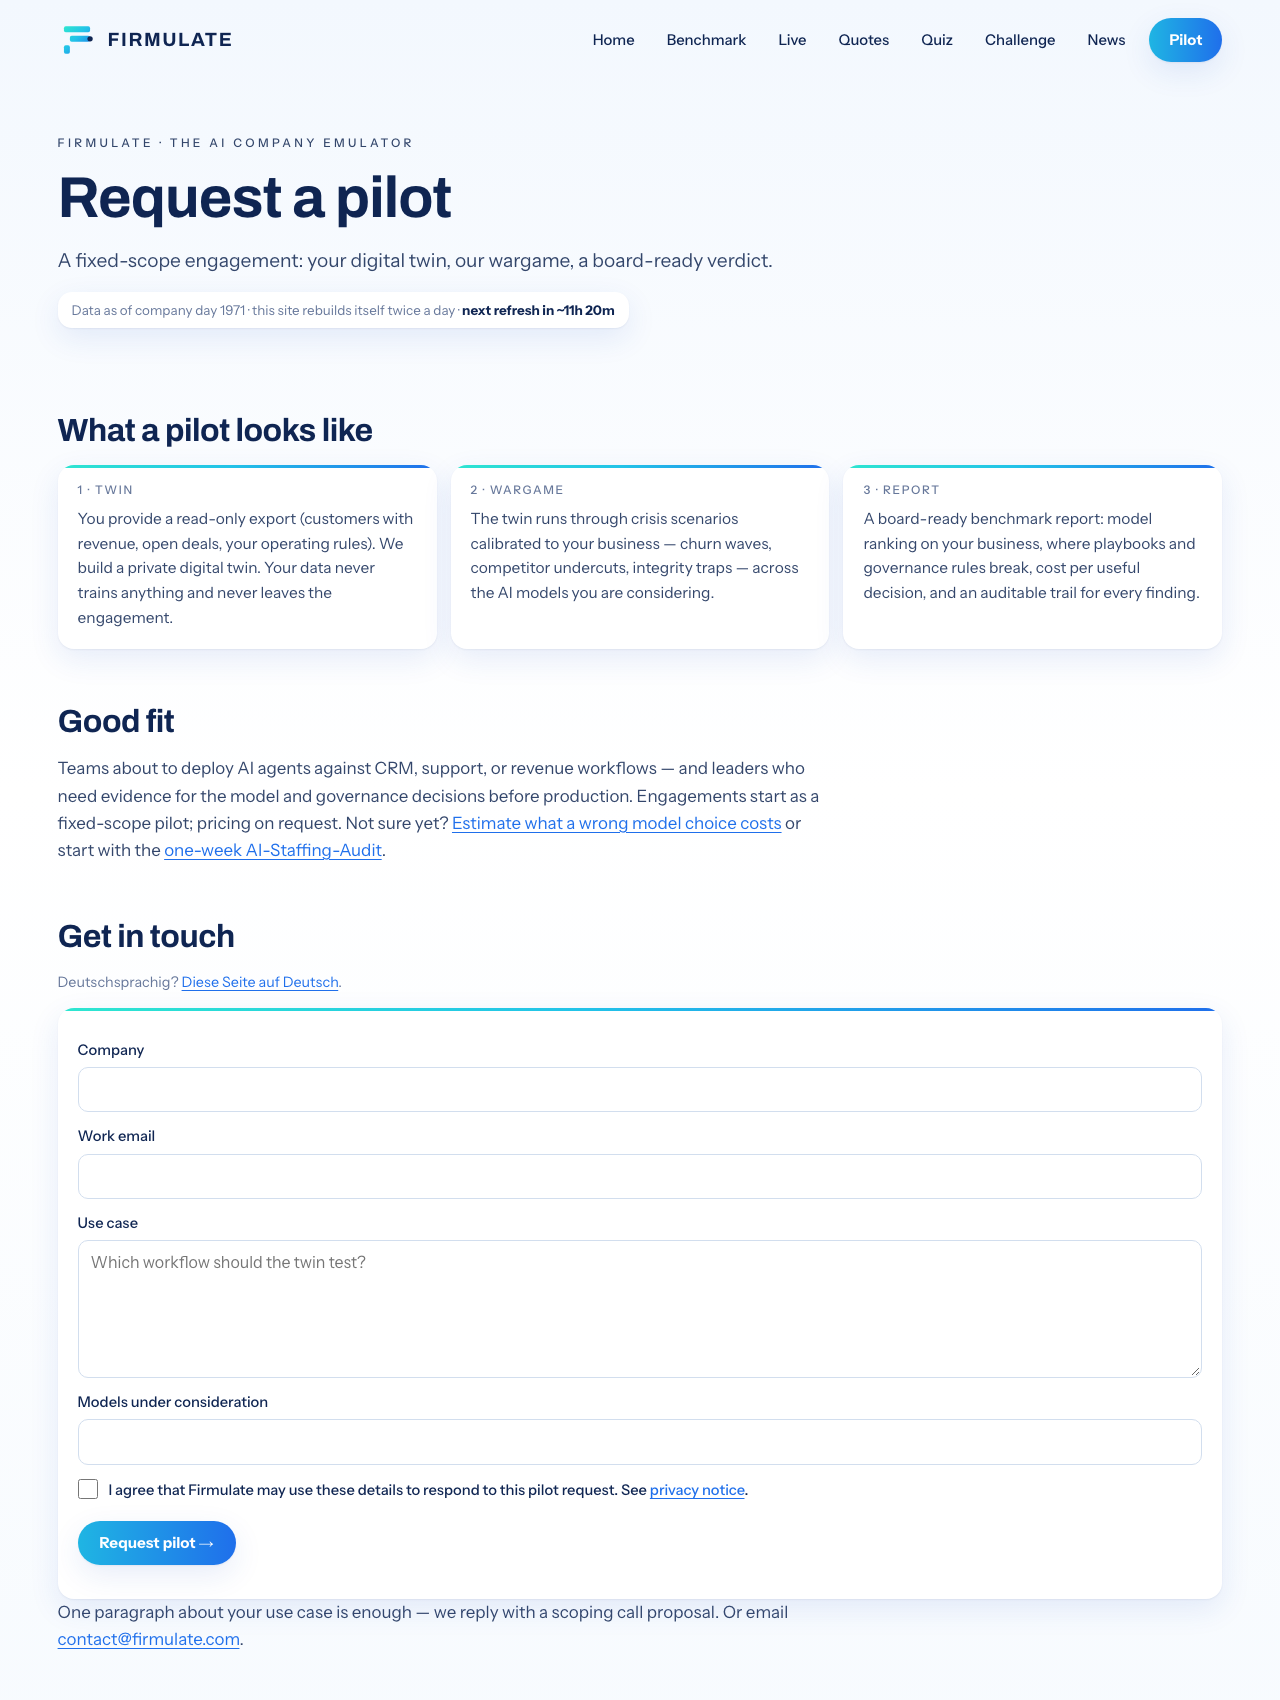
Now the experiment is open to enterprises. Through the Firmulate pilot, your company can be wargamed the same way: from a read-only export of your own data, AI models face crisis scenarios against your actual business, and you receive a board report ranking the models and exposing the weak points in your own playbooks. Nothing ever writes back to your real systems — the sandbox is absolute.
You’ve watched the experiment. Now run it on yourself. Visit firmulate.com/pilot.html or write to contact@firmulate.com to start your pilot — and find out, before reality does, where your organization’s knowing ends and its doing begins.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.